


Why enterprise grade
An app built in a weekend and a platform built for a global brand fail in the same places: an endpoint that checks who you are but not whose data you asked for, a migration nobody can roll back, a business rule nobody approved, a Monday with ten times the traffic. Enterprise teams do not avoid these by being smarter. They avoid them with process. This is the same SDLC our developers use for global brands, cut into steps your own agent can run.
It was not written for this product. The same SDLC builds large applications: enterprise systems, high-traffic e-commerce, customer-data platforms, product systems running in several countries at once. It was designed and refined over years of delivery by a team of product managers, project managers, senior architects and senior engineers at Innovate d.o.o., and what they learned is encoded in the playbooks: how a story is written, when it counts as refined, the execution rules, the coding standards, the rubrics each reviewer scores against, the dimensions of the sprint audit, the rules for a release. The MCP hands that process to your own agent, one step at a time.
- Seven gates, G0 to G7: refined, preflight, verify, review, pushed, audit, integration flows. A step that skips one is refused.
- Three independent reviewers on every change, none of whom built it.
- Due diligence across eighteen dimensions with file-level evidence, rescored after the work.
- Load testing at a year of your traffic before release, not after the first spike.
- An audit after every sprint, and a decision register for every rule nobody approved.
- The paperwork enterprises ask for: NDA, an art. 28 DPA, GDPR as home law — Innovate d.o.o., Ljubljana. When we do the work, your code and data stay in the EU; when your agent does it, your code never reaches us.
Not a repair. A way to build.
The report is where most people meet the SDLC, so it reads like a fix for what the scan found. It is not a one-off. The same process that closes the gaps is the process for every feature after them: a story with pass-or-fail acceptance criteria, a gate before it starts, verify, three reviewers, an audit at the end of the sprint, the due diligence and the load test run again. Keep building in Lovable, Replit, Base44, Bolt, v0 or by hand. Run the SDLC on the same repository, in Claude Code, Cursor or Codex. The app is built the way an enterprise builds it, from the first sprint, whichever tool wrote the first line.
- Day one, not day ninety: a new project starts with a discovery brief and a refined backlog instead of a prompt, and the first release already passes the gates.
- Every feature, the same way: what you ask your builder for becomes a story; the story cannot start until it is refined and cannot close until three reviewers have seen it.
- The score does not drift: due diligence and the load test run after every sprint, so the number you showed the client last quarter is still true this quarter.
- One licence, all your projects: one monthly licence, unlimited projects — a way of working, not a ticket for one rescue.
Works beside your builder, not instead of it. The web builders' own agents do not speak MCP, so the SDLC runs in the coding agent you already use on the exported repository — Claude Code, Cursor, Windsurf, Codex — and your builder keeps doing what it does well.
What is an SDLC — in eight frames
01An ideaIt starts as a wish: “add checkout”. 
02A story, not a promptThe wish becomes a story — who, what, why — with acceptance criteria that pass or fail. 
03The gateNothing starts until the story is refined. A step that skips a gate is refused. 
04BuildYour own agent builds it, in your repository. 
05VerifyTypecheck, lint, build and tests run, and the result is recorded before it moves on. 
06Three reviewersThree independent reviewers, none of whom built it. Any one can send it back. 
07Audit and re-scoreAfter every sprint: an audit, the due diligence and the load test, scored again. 
08Ship, and keep goingThe ledger says who did what. The loop repeats until 4 out of 5, then for every feature after.
Swipe for all eight frames. The same eight frames, every feature, every sprint.
01 Chapter 01 of 03
Production Ready
Production-ready is not a feeling. On our scale it is a number from 1 to 5, taken across five areas — data, safety, tests, review and release — and it answers one question: can real people put real money and real data into this app without it failing in a way nobody saw coming.
If you built your app with Lovable, Replit or Claude Code, it probably works. The demo is fine. What those tools do not show you is the first bad day: a customer who can read another customer’s orders, a change that cannot be rolled back, a Monday with ten times the traffic. This chapter is how that gets measured — free first, then properly — and how the number is moved until it reaches 4.
Five areas, one score
Every check we run belongs to one of five areas. Each area is scored, and the five together give the readiness score. The free scan, the due diligence and the report after every sprint all use the same areas and the same scale, so the number means the same thing wherever you see it.
Data
Whether one customer can see another’s rows, whether money and status are typed, whether a delete or a migration can be undone.
Safety
Sign-in, a role check on every route, rate limits before anything happens, secrets out of the code, an audit trail.
Tests
A suite that exists, runs on every change and walks the real flows end to end.
Review
Code that is wired up, config that is not hard-coded, business rules somebody actually decided.
Release
A pipeline that stops a bad build, health checks, jobs that survive a failure, a deploy checked against the live site.
2.0/5
Works in a demo.
The gaps sit in the foundations: in the data and in who can reach it. Do not put real users on it yet. The reference project started here.
3.4/5
The foundations hold.
Tests, a pipeline, scoped data. What remains is a known, countable list. Where the reference project stood after its first run of sprints.
4/5
Strong.
A short, bounded list stands between the app and anything we can see from the outside. This is where the loop stops.
The free scan comes first
The entry point costs nothing. Install the MCP and ask your agent whether the app is production-ready. Your agent runs 118 read-only checks against your own repository, on your own machine; our server scores what comes back and leaves an unlisted report page for seven days. Your source code never leaves your computer.
The report names every gap and what it will cost you when it bites. It never tells you what to type to fix it. That is deliberate: the diagnosis is free, and the rest of this page is how the fix is done without skipping a step. How the scan works, check by check.
Due diligence and the load test
The free tier is the end-to-end due diligence: 118 read-only checks across all five areas, then the 18-dimension technical review — every finding with file-level evidence on the 1–5 scale, a heatmap, the top risks by probability × impact — free, for any project. The SDLC then keeps it honest: the same review reads the project again across those dimensions and gives every finding file-level evidence, on the same 1–5 scale, so “security is weak” becomes a list of files and lines. The load test runs the app at a year of your traffic before release, not after the first spike.
Neither is a one-off. Both run again after every sprint, and their findings become the next sprint’s stories. That is how the number moves.
It iterates until 4/5
One pass is not the product. After every sprint, the audit's findings and the retrospective go into the next backlog as stories, and the estimates are recalibrated against what the sprint actually took. The due diligence runs again on the same eighteen dimensions, the load test runs again at a year of your traffic, and the next sprint fixes what they found. The loop repeats until the app or platform scores at least 4 out of 5 — strong — on the same 1–5 scale the due diligence uses.
How many sprints that takes depends on where the project starts. The reference project went from 2.0 to 3.4 in its first run of sprints; reaching 4 takes further sprints on the licence. The report shows the score after every iteration, so you can see which way it is moving.
Next: 02 · Proper Agentic SDLC — who does the work, and what stops them skipping a step.
02 Chapter 02 of 03
Proper Agentic SDLC
An SDLC — a software development lifecycle — is the order in which work is allowed to happen: nothing is built before it is specified, nothing is merged before it is checked, nothing ships before someone who did not build it has looked at it. Agentic means your own coding agent does the work, in your repository, where you can watch it. Our server hands out the process one step at a time, checks the preconditions before it accepts a step, and keeps the ledger of what happened and who said so.
It matters because a coding agent left to itself is a fast builder and a poor judge of its own work. It marks things done, loosens a failing test, answers business questions by guessing. The SDLC splits the job into roles that do not trust each other and puts a gate between each of them. Sign-in is free and by email; the SDLC tools unlock with the licence.
planOK
 Builder
 Verifier
 Arch
 Security
 Function
 Auditor
 DD scan
The agents and their roles
These are roles, not separate products. Your agent plays each one, and the reviewers and the auditor each start in a fresh context, so none of them judges work it wrote.
Builder
Builds exactly what the story says, in batches of three to five stories, one commit per story. A stub counts as unfinished.
Verifier
Runs the project’s own typecheck, lint, build and tests on the committed branch. Three failed attempts and the story is Blocked.
Architecture reviewer
Correctness, maintainability, fit with the existing code, and whether it holds at ten times the data.
Security reviewer
Sign-in, role and tenant on every route, input validation, data exposure, dependency risk.
Functional reviewer
Walks every acceptance criterion as the user would, with the error, loading and empty states.
Auditor
Audits the merged sprint on five dimensions. Changes nothing; reports only.
Due-diligence scanner
Nineteen dimensions with file-level evidence, before the work and after every sprint.
The reviewer rules
Every reviewer scores every criterion 0 to 5 and cites a file and line for each score; a claim without a location does not count. Any score below 3, or any critical finding, is a rejection. The functional reviewer also rejects when acceptance-criteria coverage is below 4. A change is approved only when all three approve. A rejected story goes back to build with every finding as a task; after three rework cycles it is Blocked for a person to decide, because by then the story is wrong, not the code.
The pipeline
Eleven steps, seven gates. Planning happens once per sprint, building happens once per story, and the sprint closes only when the merged work survives an audit and the journeys across it work end to end.
What happens at each step
Every step has the same shape. Your agent does the work in your repository, where you can watch it. Our server hands out the brief, checks the preconditions before it accepts a state change, and writes the result into the ledger. Skip a gate and the server says which one, and what the next allowed step is.
Discover
briefsdlc_project_init- Your agent
- Reads what exists — notes, designs, the codebase — before asking anything. States the product in one sentence, lists the core workflows per role, writes down the business rules and draws the first-release line.
- Our server
- Business questions only, three to five per round, at most three rounds; a reasonable assumption is recorded with its reasoning instead of asked. Discovery stops at 80 out of 100 confidence, or earlier if health or payment data turns up that nobody mentioned.
- You get
- A few questions only you can answer, and assumptions you can overrule.
Backlog
templatesdlc_backlog_add- Your agent
- Writes stories to one template: who, what and why; at least three acceptance criteria, including one failure case and one scope boundary; at least two tasks; an estimate on 1, 2, 3, 5, 8; a risk; an owner.
- Our server
- Validates each story and stores it as Draft with whatever is missing listed. Criteria must be pass-or-fail — never “looks good” or “is fast”. Anything above 5 points gets split.
- You get
- A backlog in plain language that someone who did not write it can mark done or not done.
Refine
G0 · refinedsdlc_refine- Your agent
- Answers the twelve-item refinement checklist per story — user and gain, scope boundary, failure paths, roles and secrets, quality targets, dependencies, tests per criterion. The questions come from the server, one story at a time.
- Our server
- Moves the story to Ready only when every item has an answer; otherwise returns the open items by number.
- You get
- Stories someone else could build without asking you anything.
Sprint plan
refined onlysdlc_sprint_plan- Your agent
- Sets one goal in business language with numbered outcomes, picks three to eight stories, orders them by dependency and checks for two stories claiming the same route or table.
- Our server
- Refuses any story that has not passed G0.
- You get
- A sprint you can read in two minutes, reviewed with you before it starts.
Build
G2 · preflightsdlc_story_start- Your agent
- Builds exactly what the story says, in batches of three to five stories — never the whole sprint first. A stub or a to-do counts as unfinished. Each story is committed with its id.
- Our server
- Checks preflight — refined, three criteria, two tasks, an owner, an estimate — then hands over the builder brief: coding standards and the definition of done. Validation at every boundary, a role check on every endpoint, the tenant from the session and never from the request.
- You get
- Nothing starts that was not fit to start.
Verify
G3 · verifysdlc_verify- Your agent
- Runs the project's own typecheck, lint, build and tests on the committed branch and reports each result as it came out. Never skips, silences or loosens a check.
- Our server
- Passes G3 only when all four pass; a skipped test counts as a failure. Each failed run is one attempt, and the third moves the story to Blocked for a person to decide.
- You get
- Stories that build and pass, and the ones that could not, stopped and named.
Three reviews
G4 · reviewsdlc_review_request · _submit- Your agent
- Runs three reviewers, each in a fresh context with its own one-time nonce. They change nothing, score every criterion 0 to 5 and cite a file and line for every score; a claim without a location does not count.
Architecture
Correctness, maintainability, fit with existing patterns, and whether it holds at ten times the data.
any score below 3, any critical finding
Security
Sign-in, role and tenant on every route, input validation, data exposure, dependency risk.
also an unauthenticated path, a committed secret, a known exploited vulnerability
Functional
Every criterion walked as the user would, edge cases, error, loading and empty states.
also acceptance-criteria coverage below 4
- Our server
- Approves only when all three approve. A rejection sends the story back with every finding as a task. After three rework cycles it is Blocked: at that point the story is wrong, not the code.
- You get
- Three independent verdicts on every change, with locations you can check.
Push, Done
G6 · pushedsdlc_story_done- Your agent
- Pushes the branch and reports the reference. Never force-pushes a shared branch, never commits secrets.
- Our server
- Marks Done only with a passed verify and an approved review on record. Done by hand is refused.
- You get
- A Done column that means what it says.
Sprint audit
G5 · auditsdlc_audit_submit- Your agent
- Audits the merged sprint in a fresh context, on five dimensions scored 0 to 5:
- Story fulfilment — every Done story meets each criterion in the merged code.
- Functional completeness — no stubs; integrations work or are switched off.
- Data integrity — migrations run forward and back, queries scoped to the tenant.
- Integration flows — each critical journey walked screen to endpoint.
- Baseline integrity — what passed before the sprint still passes.
- Our server
- Blocks completion on any dimension scoring 1 or any critical finding. Blocking findings become sprint work and the audit runs again.
- You get
- What story-level review cannot see: what broke between stories.
Integrate
G7 · flowssdlc_sprint_complete- Your agent
- Walks every critical journey the sprint touched — sign-in, the core action, error recovery — and records each as passing or failing.
- Our server
- Completes the sprint only when the audit passed and every journey passes.
- You get
- A sprint whose journeys work, not a pile of approved parts.
Report
ledgersdlc_report- Your agent
- Asks for the report and runs a short retrospective: delivered, blocked and why, estimates against actuals.
- Our server
- Renders the board, every gate row with its provenance and the open decisions, as text and as an unlisted page.
- You get
- One page after every sprint that you can send to your client, an investor or the next developer: a link and a six-character code, no account needed, no source code on it.
The gate ledger, with provenance
Every gate result is one row in the ledger: which gate, which story, the verdict, the time, a one-line summary, and where the result came from. The ledger is what the report page, the dashboard and the next sprint are built from. It is also the honest part of the product.
What “attested” means, plainly
Our server never reads your disk. When your agent says the tests passed, the server records that your agent said so. It checks the order of things — no Done without a passed verify and an approved review, no sprint without refined stories — and refuses a step that skips a gate. It cannot check that the tests really ran.
So every ledger row carries its provenance. Rows your agent reports are marked self-attested. Two paths are witnessed: CI intake, where results are read from your CI, and the reviewer panel, where our server runs the three reviews against the pull request. Those rows say so. Nothing else does, and we do not call any of it enforced.
The decision register: ship it switched off
The most expensive thing in a vibe-coded app is a business rule the model decided and the founder never saw. Here, a rule without an owner's answer is recorded the moment a story needs it — one question, answerable in one line — and the behaviour ships switched off or on a conservative default until you answer. The story still reaches Done; the sprint is not held hostage.
Your dashboard
Every SDLC licence includes the SDLC dashboard, running on your own computer over your project's ledger; what your agent does through the MCP shows up there. It is the same dashboard our own delivery runs on, with nothing held back: the board, the sprint runs, the due diligence, the decisions, the agents and what each job cost, the reports.
Ready 3
In development 2
In QA 1
In review 1
Done 12
✓ typecheck ✓ lint ✓ build ✓ tests 312 passed
rework 1/3 · attempt 1/3 · provenance: panel-witnessed
✓ typecheck ✕ lint 2 errors · attempt 1/3
2.0 → 3.4 / 5 overall
22 decided4 open
14:32 security reviewer · S-014 approve €0.41
14:29 verifier · S-016 lint fail €0.07
14:21 builder · S-017 running €1.12
14:08 architecture reviewer · S-014 approve €0.38
readiness · 0–100
Illustrative screens. Numbers and stories are an example, not a client.
What the workspace contains
- Project overview
- Product vision
- Requirements
- Discovery and document intake
- Backlog
- Board
- Story pages with their refinement
- Sprints and sprint runs
- Change requests
- Dependencies
- Design and wireframes
- Software design document
- Due diligence
- Decisions taken on your behalf, and open questions
- Agents and their jobs
- Activity log
- Cost
- Timeline
- Regression runs
- Performance
- Load testing
- Monitoring
- Infrastructure
- Releases
- Reports
- Docs
- Settings and members
Every module, on your own computer
A tour of the dashboard, module by module
The dashboard runs locally, from one line: npx https://prodready.si/dl/prodready-dashboard.tgz. It opens on your project and shows everything the SDLC records. Each module fills up as the work runs, and each one ends with what you say to your agent to fill it.
1 Before the first sprint
Project
What you want, why, and what you already have, written down before anything is built.
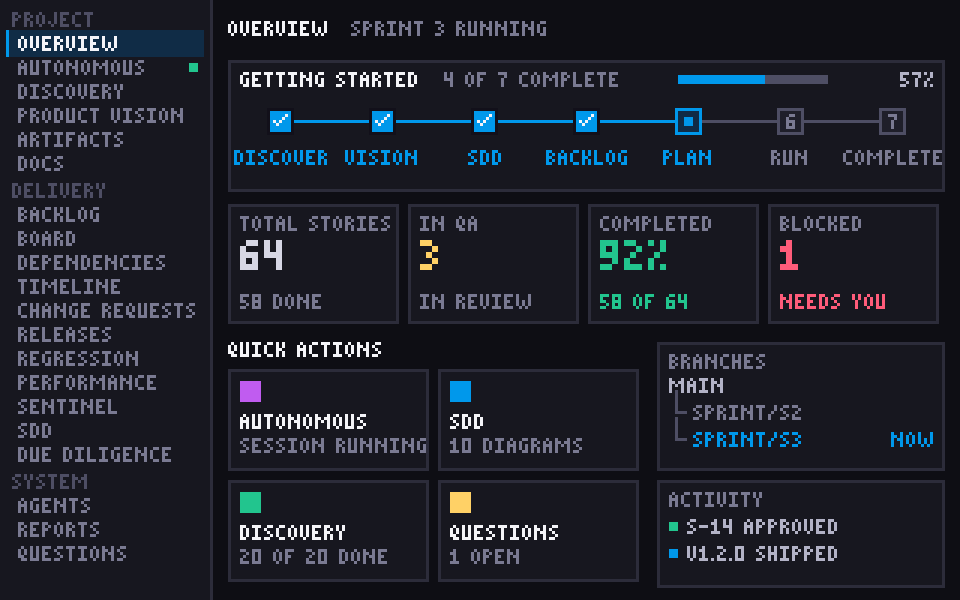
Project · 01
Overview
The first page you open. It shows where the project stands on the seven steps from discovery to a completed sprint, how many stories are done, in QA or blocked, and what happened last. You know in ten seconds whether today needs you.
Say “status”
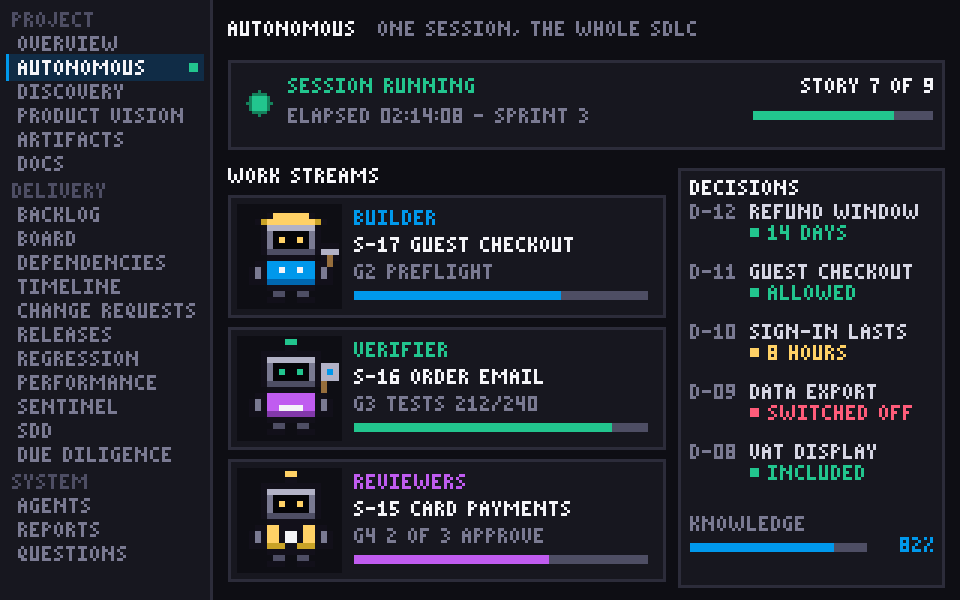
Project · 02
Autonomous
One session that walks the whole SDLC by itself: it builds, verifies, sends each change to the reviewers and moves on to the next story. You watch the work streams live and read every decision it took on your behalf, with the reason.
Say “autonomous”
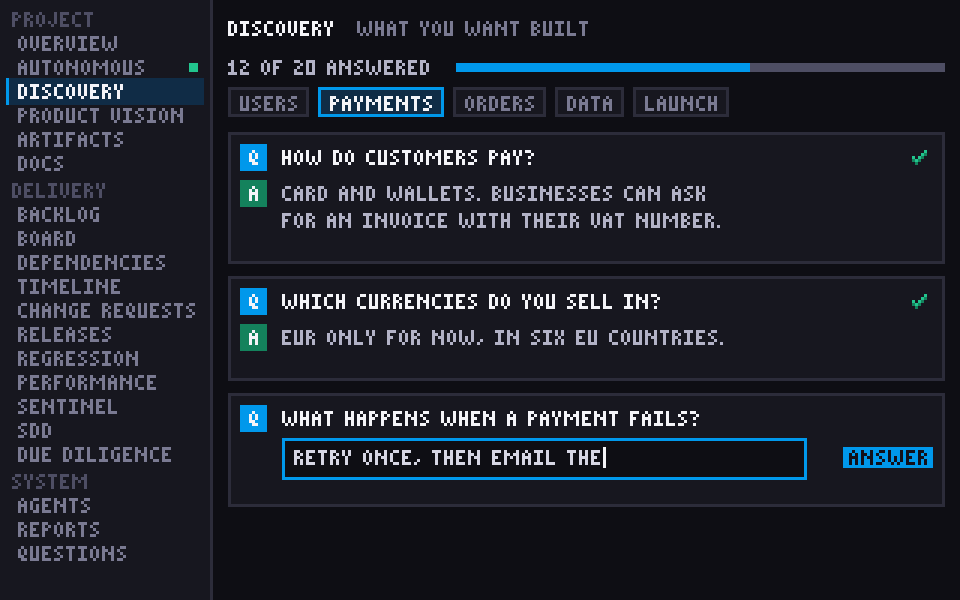
Project · 03
Discovery
Your requirements, captured as questions and answers instead of a document nobody writes. Payments, orders, data, launch: each area is asked about until nothing important is left to guess.
Say “discover”
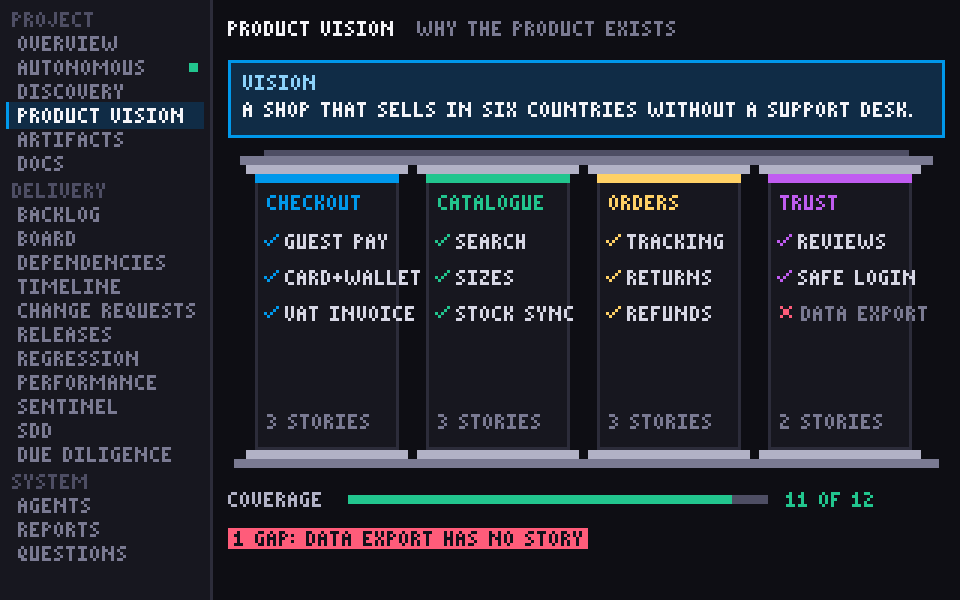
Project · 04
Product Vision
What the product is for, in one sentence, held up by a few pillars. Every feature is tied to a pillar and anything that is not gets flagged, so the backlog serves the business and not the other way round.
Say “product vision”
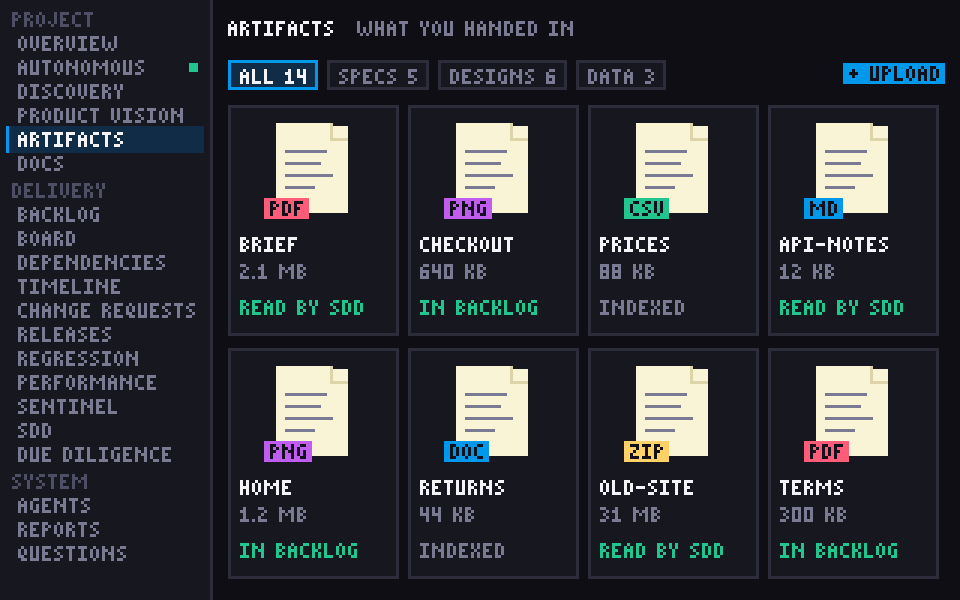
Project · 05
Artifacts
Everything you hand in, from the brief and old exports to screenshots and price lists, kept with the project. Later steps read them, so nothing you already explained is asked again.
Say “add these files”
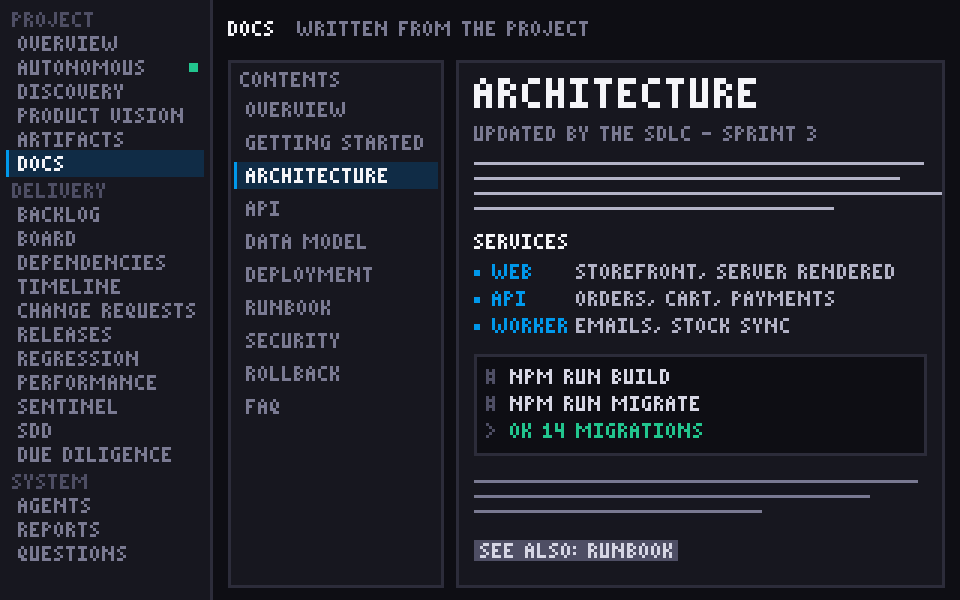
Project · 06
Docs
Project documentation written from what the SDLC already knows: architecture, API, data model, deployment, runbook. It is updated as the sprints change the code, so it does not go stale the week after it is written.
Say “docs”
2 Every sprint
Delivery
From a refined backlog to a release that is tested, measured and watched.
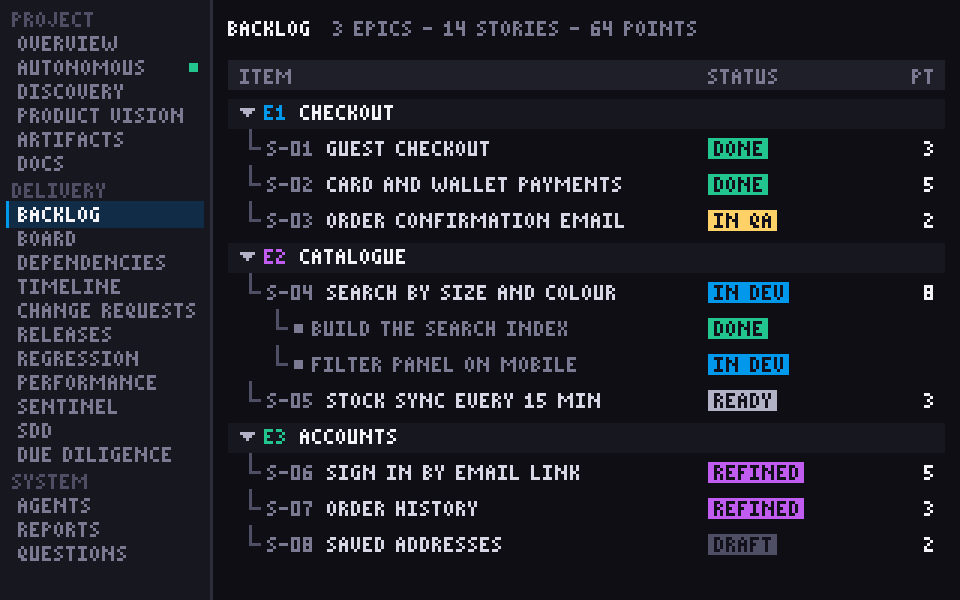
Delivery · 07
Backlog
Epics, stories and tasks in one tree. Each story is refined before anyone builds it: who it is for, what it does, and criteria that either pass or fail. The points add up to a plan you can hold the work to.
Say “create the backlog”
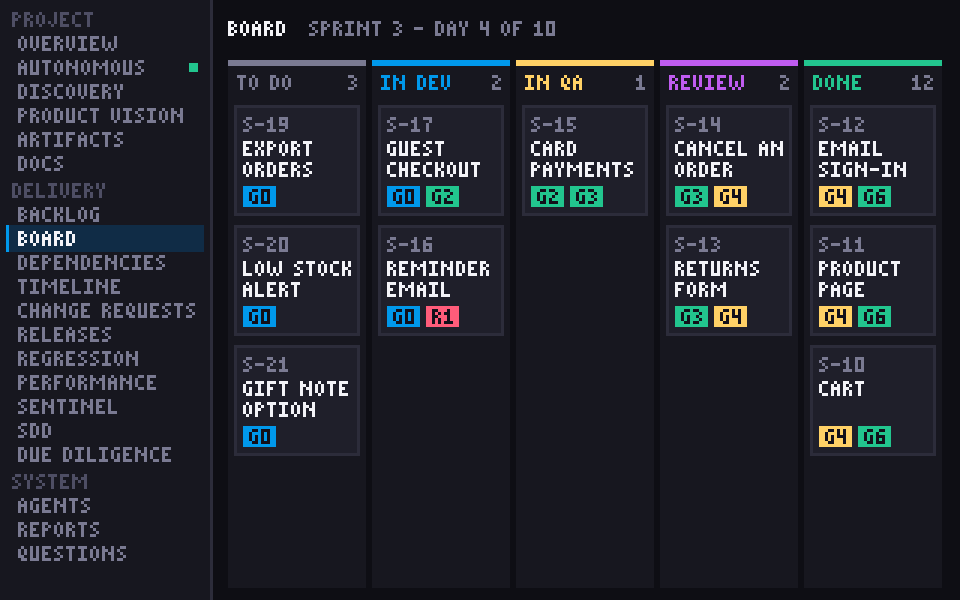
Delivery · 08
Board
The sprint at a glance: every story in its column, with the gates it has passed printed on the card. A story that failed a check shows its rework count, so nothing slides to done quietly.
Say “run the sprint”
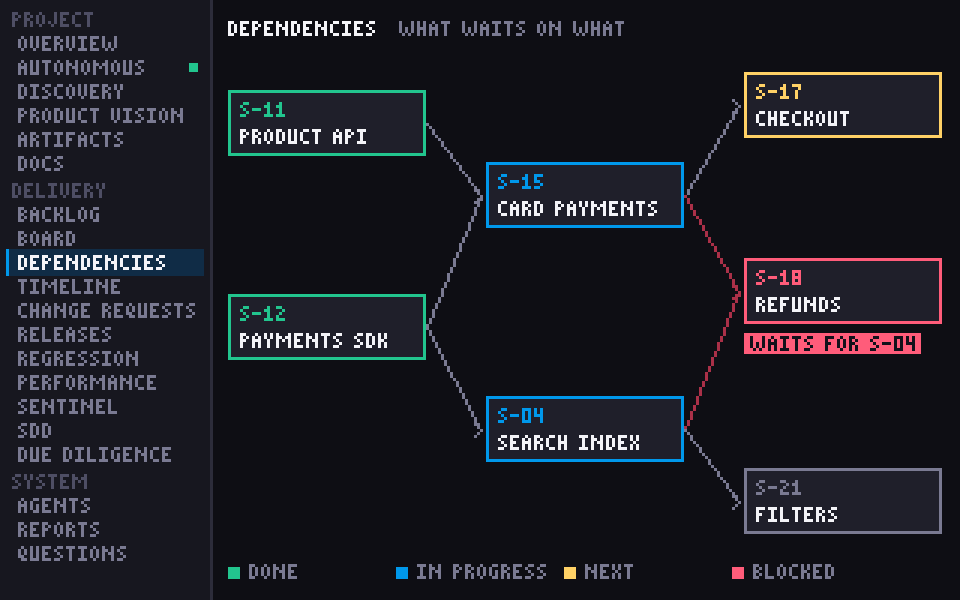
Delivery · 09
Dependencies
Which story waits on which. Work that cannot start because something else is late shows in red, with the reason, before it costs you a day.
Say “dependencies”
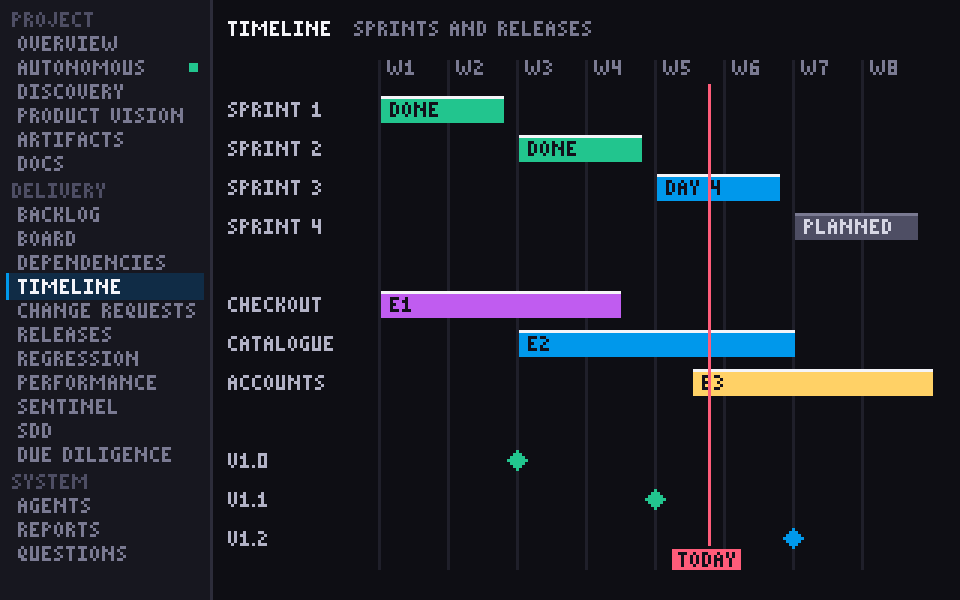
Delivery · 10
Timeline
Sprints, epics and releases on one calendar, with today marked. You see a date slipping while there is still time to do something about it.
Say “plan the sprint”
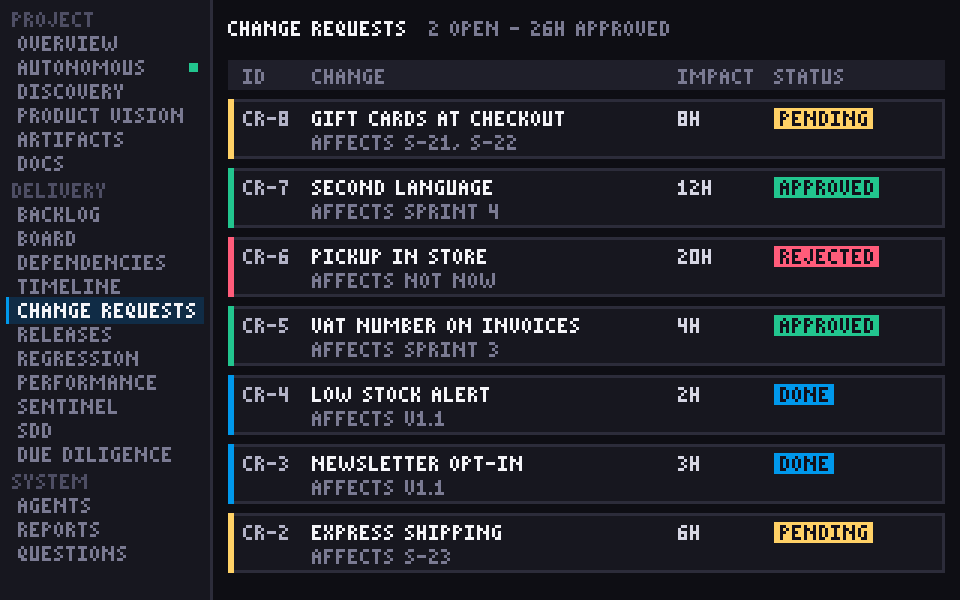
Delivery · 11
Change Requests
Every change asked for after the plan was agreed, with its impact in hours and the stories and sprints it touches. Each one gets a clear yes, no or not now, and the record stays.
Say “change request”
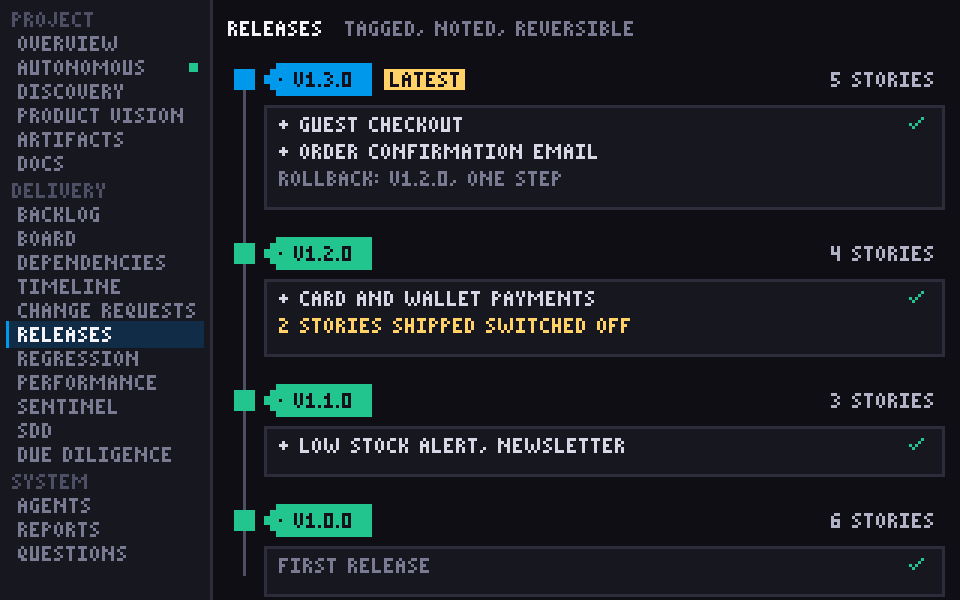
Delivery · 12
Releases
Tagged versions with their notes, the stories inside and a rollback plan. Anything shipped switched off is marked, so you know exactly what customers can see.
Say “release”
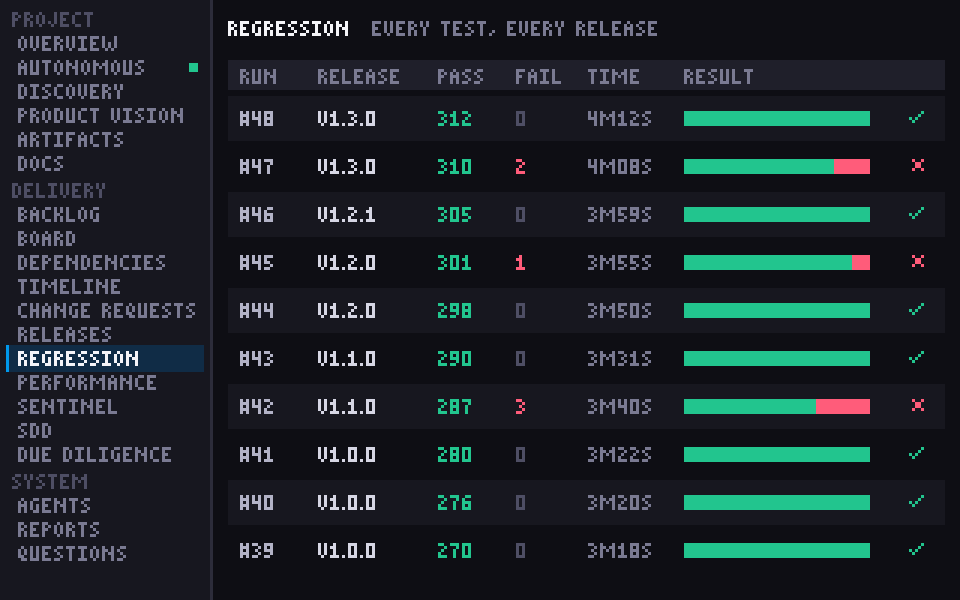
Delivery · 13
Regression
The whole test suite, run again for every release. Pass and fail per run, how long it took, and the release in which a failure first appeared.
Say “regression”
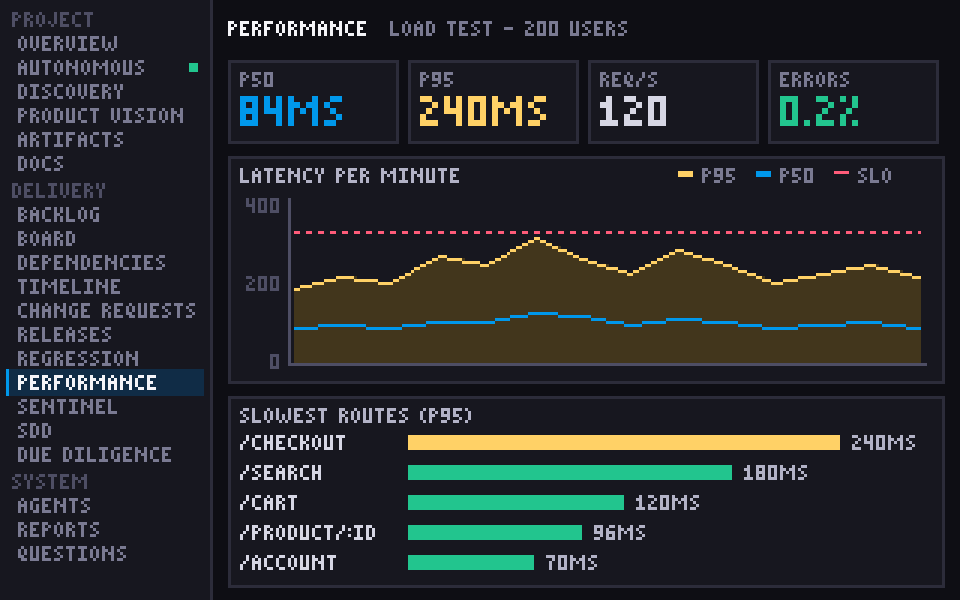
Delivery · 14
Performance
The load test: latency minute by minute, p50 and p95 against the target, the error rate and the slowest routes. You learn what a busy Monday does to the app before your customers do.
Say “performance”
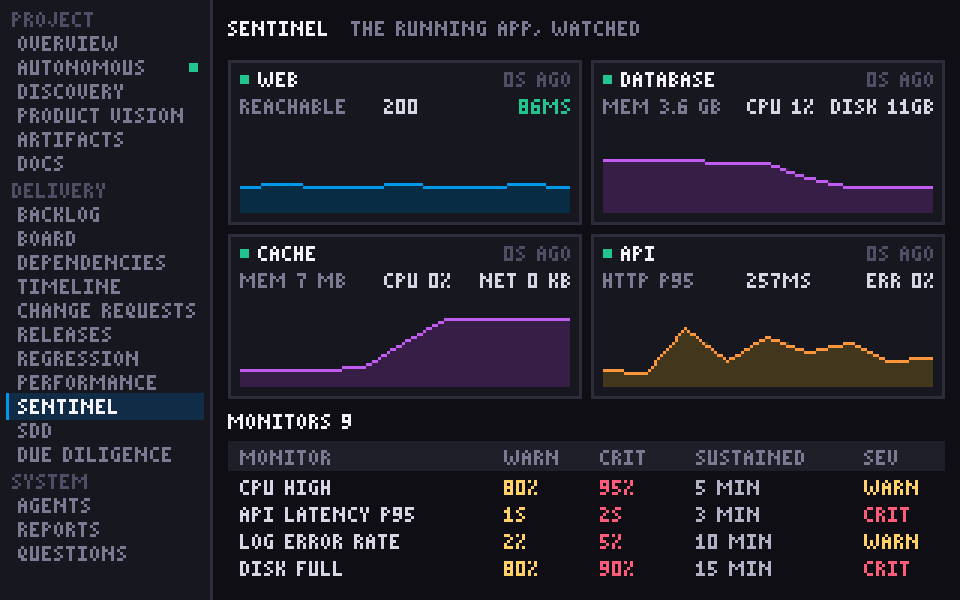
Delivery · 15
Sentinel
Watches the app once it runs: whether it is reachable, how fast it answers, how the database and cache are doing. Monitors with warning and critical levels raise the alarm when something stays wrong for too long.
Say “sentinel”
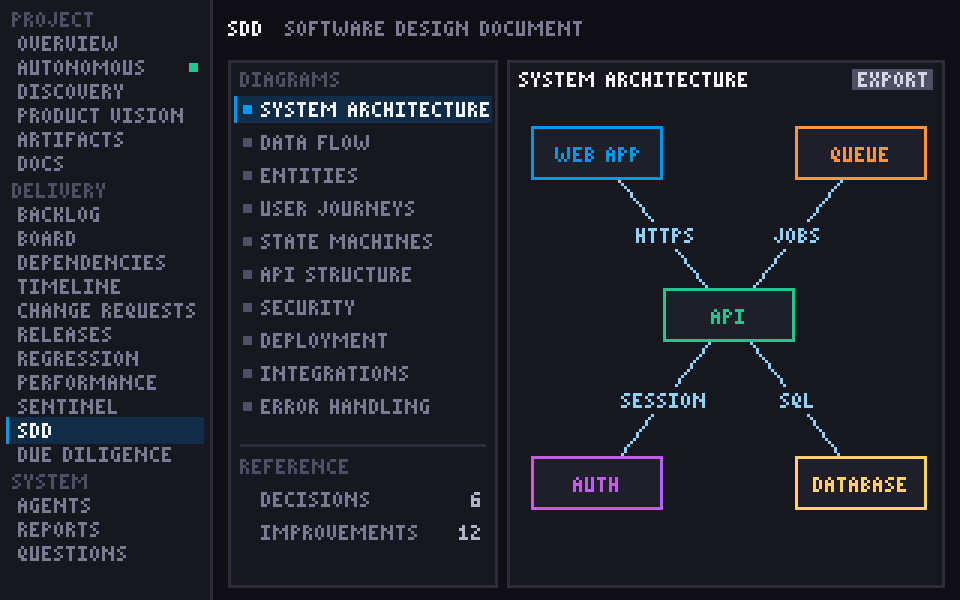
Delivery · 16
SDD
The software design document: ten diagrams, from system architecture and data flow to security, deployment and error handling, with the decisions behind them. A new developer or an auditor reads one document instead of the code.
Say “SDD”
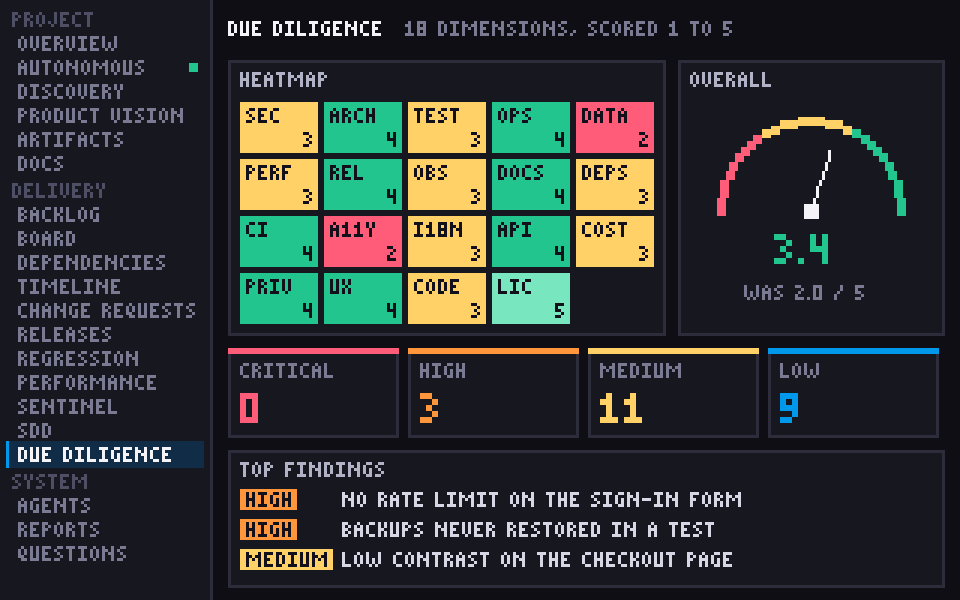
Delivery · 17
Due Diligence
Nineteen dimensions scored from 1 to 5, the findings by severity and one overall score, before and after. It is the number investors and enterprise buyers ask for, with the evidence behind it.
Say “due diligence”
3 Around the team
System
Who is doing the work, how fast it goes, and what only you can decide.
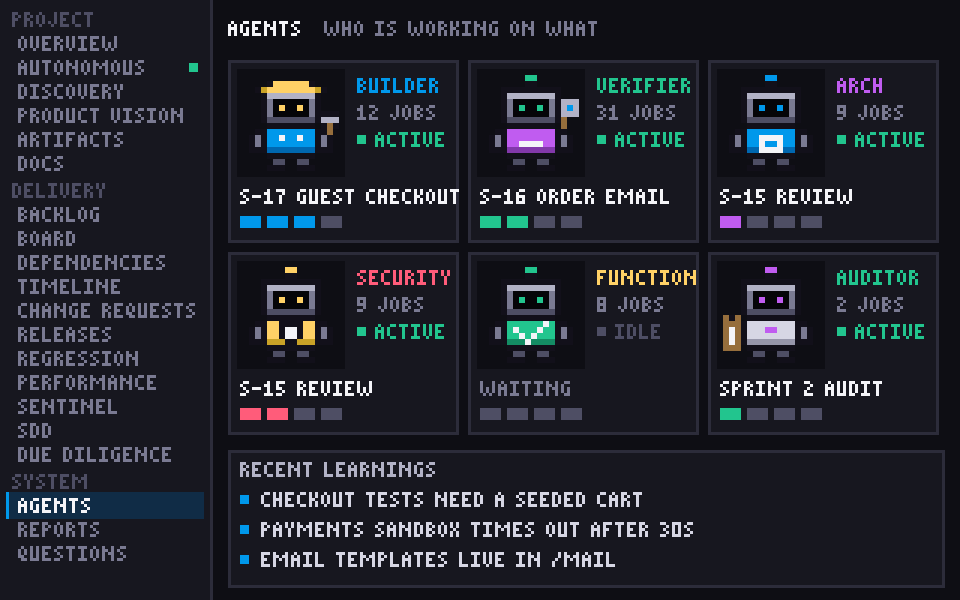
System · 18
Agents
Every role on the team: the builder, the verifier, the three reviewers and the auditor. What each one has in hand right now, how many jobs it has run, and what it has learned about your project along the way.
Say “who is working on what”
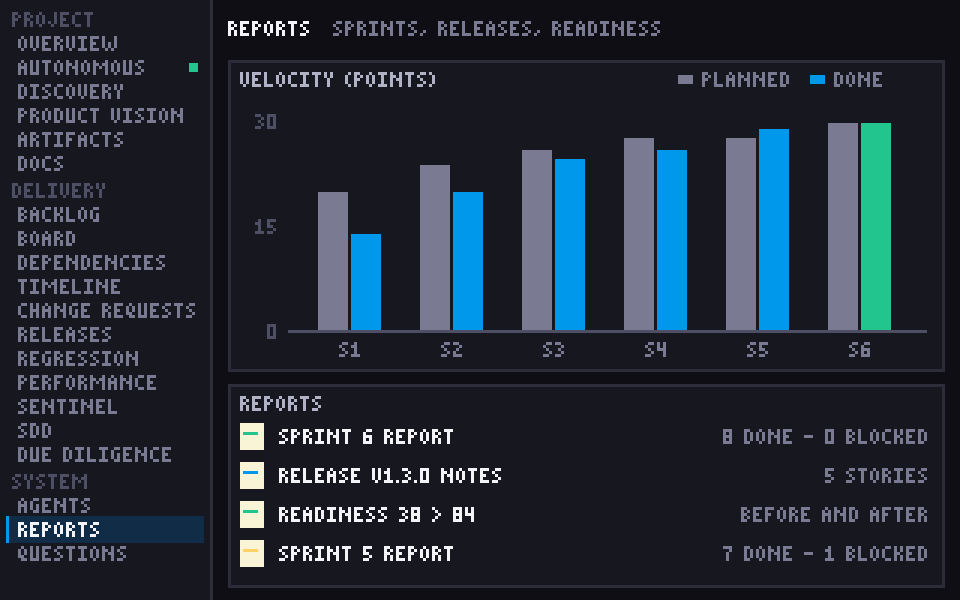
System · 19
Reports
Velocity sprint by sprint, planned against done, a report for every sprint and every release, and readiness before and after. The page you send to your client, a co-founder or an investor, after every sprint.
Say “report”
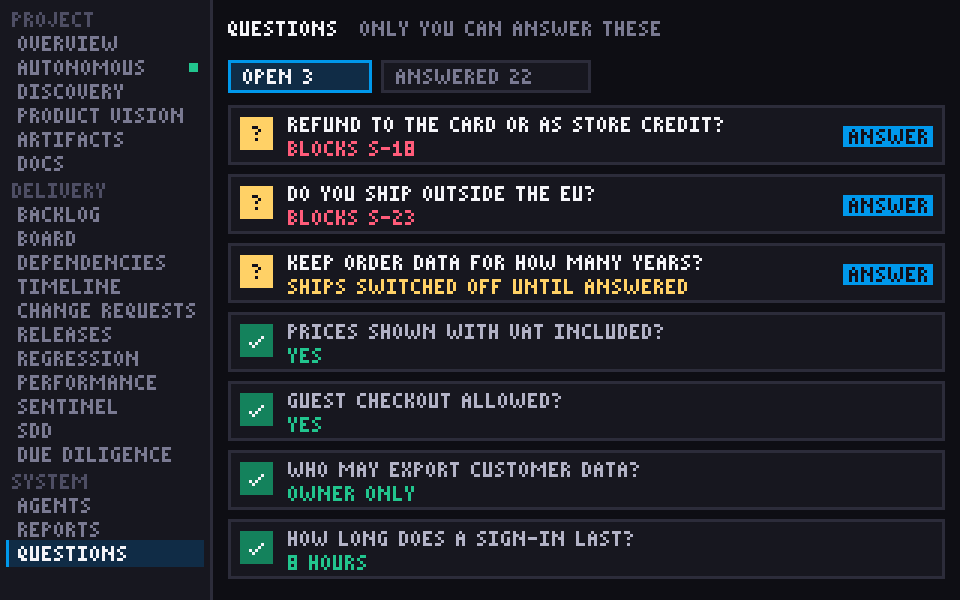
System · 20
Questions
The business questions only you can answer: refunds, shipping, how long data is kept. Until you answer, the feature ships switched off or stays blocked, so nothing is guessed on your behalf.
Say “questions”
Illustrative pixel screens of the real modules. The shop shown is an example, not a client.
The tools, step by step
Forty-nine sdlc_* tools, mapped to the steps in the order a project meets them. Your agent calls them; you never have to — you say what you want in plain words. When it is unsure what comes next, sdlc_status names the next allowed step. The five marked free work without a licence, so an account can always see, export and delete its projects; pausing or stopping an autonomous run is free too.
| Step | Tools | Gate |
|---|---|---|
| Account | sdlc_licence_statussdlc_request_accesssdlc_project_listsdlc_project_delete | free |
| Any step | sdlc_playbooksdlc_status | brief · next step |
| Discover | sdlc_project_initsdlc_discovery | GD |
| Scope | sdlc_scope_setsdlc_sow_create | statement of work |
| Vision | sdlc_vision_set | feature map |
| Journeys | sdlc_journeys_set | coverage |
| Wireframes | sdlc_wireframes_set | completeness |
| Architecture (SDD) | sdlc_design_set | decision records |
| Docs | sdlc_docs_record | generated |
| Import | sdlc_backlog_importsdlc_backlog_addsdlc_contract_set | template |
| Refine | sdlc_refinesdlc_refine_all | G0 |
| Plan | sdlc_sprint_plansdlc_success_predict | refined only |
| Sprint | sdlc_sprint_start | sprint brief |
| Story | sdlc_story_startsdlc_verifysdlc_review_requestsdlc_review_submitsdlc_story_done | G2 · G3 · G4 · G6 |
| Decisions | sdlc_decision_addsdlc_decision_resolve | register |
| Audit | sdlc_audit_requestsdlc_audit_submitsdlc_sprint_complete | G5 · G7 |
| Retro | sdlc_sprint_retro | estimates vs actuals |
| Readiness | sdlc_dd_recordsdlc_perf_recordsdlc_monitoring_record | trend · G8 |
| Release | sdlc_release | staging · your yes |
| Autonomous | sdlc_autonomous | every gate above |
| Side lanes — used whenever they are needed | ||
| Bugs | sdlc_bug_reportsdlc_bug_detectsdlc_sprint_harden | G3 sweep |
| Hotfix | sdlc_hotfix_start | G2–G6, no shortcut |
| Change requests | sdlc_change_request | your yes |
| Risks | sdlc_risk_set | bands |
| Analytics · cost | sdlc_sprint_analytics | velocity · effort |
| Dashboard · export | sdlc_dashboardsdlc_reportsdlc_project_export | your computer |
Autonomous mode
You do not have to drive every step. In autonomous mode your agent first refines the whole backlog on autopilot — every answer taken from your documents and the code, with its reason — and then loops on its own: build, verify, three independent reviews, done, the sprint audit, the next sprint. It keeps going until one of three things happens: a question comes up that only you can answer, it reaches a limit you set (stories, sprints or minutes), or you say SDLC off. Business questions that can wait are filed as decisions and ship switched off; nothing skips a gate because nobody is watching.
- Start it: say SDLC autonomous or run it unattended for one sprint, or type
/prodready:autonomous. Refinement alone: refine everything on autopilot, or/prodready:refine-all. - Watch it: the dashboard's Autonomous page shows the session and its limits, the work streams, and the open questions. Answer any of them whenever you like with answer D-4: … and the run picks it up.
- Stop it: SDLC off or pause. Nothing is lost; resume carries on from the same step.
Next: 03 · Agile Methodology in the Agentic World — how the work is cut, planned and learned from.
03 Chapter 03 of 03
Agile Methodology in the Agentic World
Agile is how teams keep a large piece of software moving in small, checkable steps: a backlog of stories written so anyone can tell whether they are done, sprints with one goal, an honest look back after each one. When agents write the code, none of that goes away. It matters more, because an agent builds whatever it is given, quickly, including the wrong thing.
If you built with Lovable, Replit or Claude Code, you already work in prompts. A prompt is a story without acceptance criteria. The SDLC turns what you asked for into a refined backlog, plans it into sprints, audits what each sprint actually did and feeds what it learned into the next one. Your part is the product owner’s: decide, in one line, what only you can decide.
A refined backlog
Every story follows one template: who it is for, what they can do afterwards and why it matters; at least three acceptance criteria, including one failure case and one scope boundary; at least two tasks in build order; an estimate, a risk and an owner. A criterion is pass-or-fail or it is not a criterion — never “looks good”, never “is fast”.
A story is Ready only when it answers all twelve questions of the refinement checklist. That is gate G0, and nothing enters a sprint without it.
- R1The user and the gain
- R2One sentence, one deliverable
- R3Size
- R4Criteria that name the exact thing
- R5The scope boundary
- R6Failure paths
- R7Roles, boundaries, secrets
- R8Quality targets
- R9Design reference
- R10Dependencies and open decisions
- R11Tasks in build order
- R12Tests per criterion
The questions themselves come to your agent from the server, one story at a time, with the licence. A story answers all twelve or it stays Draft.
Sprint planning
- Three to eight refined stories. A story that has not passed G0 is refused.
- One goal in business language, broken into numbered outcomes. Every story claims an outcome, and every outcome has a story.
- Ordered by dependency: data before server, server before screens, core flows before the advanced ones. Two stories that claim the same route or table are merged or put in order.
- A buffer of ready stories that can slip to the next sprint: 10, 20 or 30 percent, by risk.
- Reviewed with you before it starts: scope, order, estimates, risks. Two minutes of reading.
The sprint cycle
- Refine each story and check the sprint against its goal. G0
- Plan the sprint: goal, outcomes, stories, order, who builds and who reviews.
- Start the sprint.
- Build in batches of three to five independent stories, each through preflight first. G2
- Verify each story: typecheck, lint, build, tests, up to three attempts. G3
- Three independent reviews per story, up to three rework cycles. G4
- Push each approved story and mark it Done. G6
- Open business decisions go into the register the moment they appear; the code ships with them behind a switch.
- Audit the merged sprint on five dimensions; fix what blocks and audit again. G5
- Walk the critical journeys end to end and complete the sprint. G7
- Report, and hold a short retrospective: delivered, blocked and why, estimates against actuals.
- Carry what was learned into the next backlog, re-run the due diligence and the load test, and go again until 4 out of 5.
Sprint audits and the retrospective
Story reviews see one change at a time. The sprint audit sees what broke between them. An independent auditor, in a fresh context, scores the merged sprint 0 to 5 on story fulfilment, functional completeness, data integrity, integration flows and baseline integrity. Any dimension at 1, or any critical finding, blocks the sprint until it is fixed and audited again (step 09).
Then the retrospective, which is short and written down: what was delivered, what was blocked and why, what the estimates said against what the sprint took. Its findings, the audit’s and the due diligence’s become stories in the next backlog. Nothing learned is left in a chat window.
Estimates and velocity
Stories are sized in points on 1, 2, 3, 5 and 8 — the build effort of one story, including reading the code, verifying and one retry, not human hours. Anything at 8 is split before it is planned. Known complexity moves the estimate one step up; a pattern already delivered in the project moves it down. Estimates are never padded, and identical estimates on every story mean nobody estimated.
Each plan states its points, and each report sets what reached Done against what was planned. That is the velocity the next sprint is sized against. When actuals run above one and a half times the estimates, the reference sizes are recalibrated; below 0.7 times, they are tightened.
Your job: product owner
You do not write stories, estimate, build, test, review or audit. You answer the business questions only you can answer — a few in discovery, then one at a time as stories need them — each in one line. Until you answer, the behaviour ships switched off or on a conservative default, and the sprint carries on. You read the plan before a sprint starts and the report after it ends. That is the whole job.
A sprint, as a transcript
Condensed from one session in Claude Code on a booking app. Tool calls are shown by name; the agent's work between them — editing files, running tests — happens in the terminal as usual.
> Set this repo up on the SDLC. First goal: customers can cancel their own bookings.

▸ sdlc_project_init {name: "booking", stack: ["nextjs","postgres"]}
  → project k3F9xQ2a · discovery brief
Three questions before I write stories:
  1. Can a customer cancel at any time, or only up to a cutoff?
  2. Is a cancellation inside the cutoff refunded?
  3. Who gets notified — the customer, the business, both?
> Up to 24 hours before. Both get an email. Refunds — I haven't decided.

▸ sdlc_backlog_add 4 stories
  → S-001 … S-004 stored as Draft · S-003 has 2 criteria, needs ≥ 3
▸ sdlc_decision_add "Is a cancellation inside 24 h refunded?" asked_by: owner
  → D-001 open · ships as: switched off
▸ sdlc_refine S-001 … S-004
  → G0 pass ×3 · S-003 open: R5 (scope boundary), R12 (tests per criterion)
[agent adds the boundary and a test per criterion]
▸ sdlc_refine S-003 → G0 pass · Ready
▸ sdlc_sprint_plan goal: "Customers cancel their own bookings" · S-001 … S-004
▸ sdlc_sprint_start SP-1 → active

▸ sdlc_story_start S-002 "Customer cancels a booking up to 24 h before"
  → G2 pass · builder brief · In Development
[agent builds on its branch, commits "S-002 …"]
▸ sdlc_verify S-002 → G3 fail · lint: 2 errors · attempt 1 of 3
[agent fixes the two lint errors in the story's files]
▸ sdlc_verify S-002 → G3 pass · tests 48 passed, 0 failed · In QA

▸ sdlc_review_request S-002 → 3 briefs, 3 nonces, run each in a fresh context
▸ sdlc_review_submit architecture → approve · min score 4
▸ sdlc_review_submit security → reject · auth 2
    high: DELETE /api/bookings/[id] checks sign-in, not that the booking belongs to the caller's account — app/api/bookings/[id]/route.ts:41
▸ sdlc_review_submit functional → approve · ac_coverage 4
  → G4 reject · back to In Development · 1 task · rework cycle 1 of 3
[agent scopes the query to the session's account, adds a test for another account's booking]
▸ sdlc_verify S-002 → G3 pass · 50 passed
▸ sdlc_review_request S-002 → 3 new nonces
▸ sdlc_review_submit ×3 → approve · approve · approve
  → G4 approve
▸ sdlc_story_done S-002 pushed_ref: 9c41e7a → G6 · Done
[S-001, S-003, S-004 the same way]

▸ sdlc_audit_request SP-1 → 5 dimensions
▸ sdlc_audit_submit 4 · 4 · 3 · 4 · 4 · refund path deferred (D-001, switched off)
  → G5 pass
▸ sdlc_sprint_complete SP-1 flows: sign in → book → cancel pass · cancel inside 24 h → refused with message pass
  → G7 · SP-1 completed
▸ sdlc_report → 4 stories Done · 1 verify retry · 1 review rework · 1 open decision · report page /r/k3F9xQ2a

> Refunds inside 24 hours: no.
▸ sdlc_decision_resolve D-001 → decided · story S-005 planned to switch it on
Notice what did not happen. The agent did not mark its own work Done. The refund question did not stall the sprint, and did not get answered by a guess.
The same method, at scale
None of this was invented for apps built in a weekend. It is the methodology our product managers, project managers, senior architects and engineers use to deliver large applications: enterprise systems, high-traffic e-commerce, platforms running in several countries at once. The backlog template, the refinement checklist, the estimation scale, the reviewer rubrics and the audit dimensions are theirs, written down after years of delivery. The only difference here is who sits at the keyboard.
What you get
- 49 SDLC tools and 26 commands in the MCP host you already use, including autonomous mode.
- A gate ledger with provenance: every result, its time, its verdict and where it came from.
- A decision register: open rules, who decides, how each ships meanwhile.
- A refined backlog: pass-or-fail criteria, tasks, estimates, risks, owners.
- Three independent reviews per change, scored with file and line.
- Sprint audits on five dimensions, re-run until nothing blocks.
- A load-test gate before release.
- The dashboard on your own computer with the board, sprint runs, reports and everything above.
- A sprint report page per project.
- Readiness before and after: the free scan on day one and after the last sprint.
Pricing
The enterprise-grade due diligence is free. Everyone who signs up by 31 December 2026 gets the SDLC free for 3 months from their sign-up (the next 10,000 users who sign up; we end the offer once those 10,000 have joined); after that the licence — $30 a month, or €27 in the EU, cancel any time, unlimited projects — is on the pricing page, with the payment link and a comparison against an agency sprint.
Short answers
Which hosts does it work in?
Any MCP host that speaks streamable HTTP with OAuth: Claude Code, Claude Desktop, Codex, and Cursor, Windsurf or Cline through mcp-remote. The install line for each is on the start page.
What leaves my machine?
What your agent sends: story text, decisions, pass or fail with one-line summaries, review scores and findings with file and line. Not your source files. The project document stays on our server so the ledger survives between sessions; sdlc_project_delete removes it. The reviewer panel, if you use it, reads the diff of the pull request it reviews.
Can I cancel?
Yes, at any time. The licence is monthly; it runs to the end of the month you paid for, then the SDLC tools lock again. The free scan keeps working, and your projects can be deleted whenever you like.
What if my agent is weak?
Then it fails more gates. That is the point: a weak agent that cannot pass verify in three attempts stops at Blocked instead of shipping, and three reviewers in fresh contexts catch what the builder talked itself into.
What does “attested” mean?
That your agent reported the result and the ledger records it as such. The server checks order, not the truth of a test run. CI intake and the reviewer panel are the two witnessed paths; everything else is marked self-attested.
Do I need GitHub?
No. Sign-in is an emailed link. The pipeline needs a git remote your agent can push to, so a pushed reference can be recorded; any host will do.
Is the code mine?
Yes. Your agent writes it in your repository; we never hold a copy. What we hold is the project document — stories, decisions, the ledger — and that is yours to export or delete.
Install the MCP. Run the free enterprise-grade due diligence tonight.
Sign-in is by email and free. The due diligence tells you what is wrong; the  prodready SDLC is how your agent fixes it without skipping a step — one licence, unlimited projects.